[–] consumer451 1 day ago
Link to comment explaining the discovery:
https://old.reddit.com/r/Seattle/comments/1xhf6qp/archivetod...
edit: Maybe I should have titled this "claim to have discovered" as there is no external verification, and no write up. I thought I should post this in any case.
[–] shagie 1 day ago
Archive.today is directing a DDoS attack against my blog https://news.ycombinator.com/item?id=46843805 (8 months ago, 366 points, 178 comments)
Ask HN: Weird archive.today behavior? https://news.ycombinator.com/item?id=46624740 (9 months ago, 140 points, 71 comments)
[–] no-name-here 1 day ago
I presumed DDoS was used colloquially, but no, they literally added JS so every visitor made a request every 0.3 seconds to that blog server, in response to a blog article. Wholly malicious based on the reporting.
[–] consumer451 1 day ago
https://www.reddit.com/r/Seattle/comments/1xhf6qp/archivetod...
[–] Vaushite 1 day ago
[–] neuronexmachina 1 day ago
[–] oytis 1 day ago
[–] dspillett 1 day ago
I particularly dislike the fact that I was, unbeknownst to me at the time, was coopted as part of that brigade of brick throwers.
--------
[1] a significant chuck of the internet
[2] beat up his online resources
[–] consumer451 1 day ago
I always respect the "don't editorialize" rule, but felt that this was a special case as the post title is so sub-reddit specific. My original post title was along the lines of "r/Seattle mods discover archive.today injecting malware, ban site.
[–] mahboi 1 day ago
I'm confused though, it says the site injected malware into its archived form. But the HN title says archive.today injected the malware.
[–] LoganDark 1 day ago
[–] mahboi 1 day ago
Idk, maybe this is just a typo, but grammatically this is saying the article injected the links.
[–] k00shball 1 day ago
(To be fair, that isn't the only redirect so you might need to click it a few times.)
[–] deepfriedrice 1 day ago
Whereas other links (e.g. the immediate next one to arxiv) seem unaffected.
edit: That was a red herring. It seems to redirect all .pdf links I try that don't point to a valid snapshot. Very interesting.
[–] mahboi 1 day ago
[–] opello 1 day ago
Just for the sake of preserving what I did see, the URL linked in the text was:
https://archive.ph/o/jXv3A/https://schenklawfirm.com/wp-content/uploads/2026/10/wan-v-openai-complaint.pdf
https://archive.ph/https://schenklawfirm.com/wp-content/uplo...
[–] grimgrin 1 day ago
[–] RunSet 1 day ago
And it is federated so when the biggest Lemmy instance starts to suck, Lemmy can be the Lemmy replacement, too.
I understand that mentioning it on popular subreddits is verboten.
[–] Vaushite 17 hours ago
[–] ranger_danger 12 hours ago
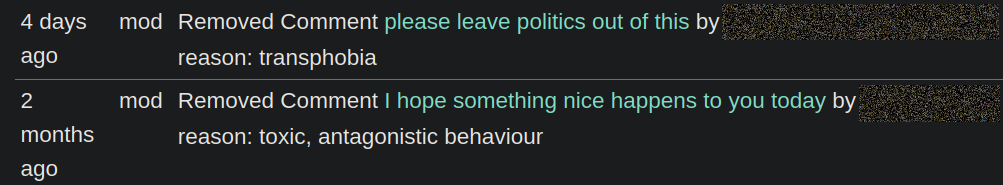
Many servers defederate from each other regularly, making it very much a "which wind would you like to piss into" situation where you have no idea who (if anyone) is even seeing your messages.
[–] consumer451 1 day ago
[–] Akronymus 1 day ago
[–] qingcharles 1 day ago
[–] kuschku 1 day ago
[–] qingcharles 9 hours ago
[–] mschuster91 1 day ago
That's the entire reason I use old.reddit - the New Reddit backend is a pile of unreliable dung. Just like everything that is made with GraphQL.
[–] abeyer 1 day ago
[–] consumer451 1 day ago
https://www.reddit.com/r/Seattle/comments/1xhf6qp/archivetod...
[–] strenholme 1 day ago
https://archive.ph/HcOq2 (This is a link to the post for this article)
(If one’s ISP can’t access archive.today, I find that Firefox’s built in free VPN can usually access them)
Or, you can use on of the various Reddit scrapers, e.g:
https://redlib.catsarch.com/r/Seattle/comments/1xhf6qp/archi...
Here’s a list of Reddit scrapers:
https://github.com/redlib-org/redlib-instances/blob/main/ins...
Personally, as scummy as archive.today is at times, I can generally trust them to have an honest archive about, say, someone’s drunk post before said drunk deletes the post.
[–] mahboi 1 day ago
[–] abeyer 1 day ago
But even aside from opinions on their UX, they're aggressively experimenting with the login more... Even on the new UI I now semi-regularly see that I can read the initial post and one or two comments but as soon as I scroll past or try to expand a comment thread get a login prompt.
[–] drusepth 1 day ago
[–] paulpauper 1 day ago
[–] lxe 1 day ago
Previous HN thread:
[–] surround 1 day ago
It redirected me to https://stolidityseashellshotter[.]com/ezrsb5dd1268e6f6ebaad... which then redirected me to a fake clone of RT news: https://rurtnews[.]com/
Unlike the Reddit mods, I'm not getting redirected to the malware site, just the fake RT site.
Edit: I clicked it a few more times and its redirecting me to either the fake RT or https://gullible-thanks[.]com/w5FDGi, which redirects to either https://sportshard[.]com/ or https://eatcells[.]com/land/?token=[a random string]
I had to disable uBlock Origin, since it does something to block many of these redirects.
[–] avidruntime 1 day ago
[–] tyrabound 1 day ago
[–] qingcharles 1 day ago
[in fact, I just tried btdig.com and it tried to redirect me to the same site: guillible-thanks.com or whatever]
[–] iam-py-test 13 hours ago
[–] qingcharles 13 hours ago
[–] iam-py-test 13 hours ago
[–] qingcharles 9 hours ago
[–] consumer451 1 day ago
Well, this got on the front page of HN... Such things make even FAANG behemoths pay attention. What I mean is, who knows what happened since r/Seattle called it out.
Does some other archive, archive the archiver?
There might be a cryptographic solution for this problem, but that's far beyond my knowledge set.
Also, as the peer comment pointed out, it could be geo-scoped. You know, like a targeted attack.
The entire reason that I posted this originally is that I cannot think of a juicier userbase than HN. We all post archive.is links every single time. Given that operator's history, we are doing the link-click analogy of pasting shell commands from the web into our terminals. We should know better by now, but complacency leads to ___.
[–] efficax 1 day ago
[–] consumer451 1 day ago
https://www.reddit.com/r/Seattle/comments/1xhf6qp/archivetod...
[–] avidruntime 1 day ago
Edit: Another r/seattle moderator (not the OP of the original post) has posted their technical writeup of the malware, which is detailed and definitely more in line with what we'd expect with this kind of PSA. While I stand by all criticisms of the OP moderator and their initial handling of the disclosure, you can find the details of the incident in this excellent write up: https://www.reddit.com/r/Seattle/comments/1xhf6qp/archivetod...
[–] no-name-here 1 day ago
[–] RobotToaster 1 day ago
[–] no-name-here 23 hours ago
> … a blog post from 2023, where the researcher looked into what makes Archive Today tick.
> The exposé reads as mostly positive, even suggesting that folks donate to Archive Today, as it provides a valuable service to the online community. Among the post's contents, Patokallio shows relatively slim and unverified findings about the Archive's operator's (or operators') identities and their income sources.
Is your argument that it's legitimate to intentionally cause user's PCs to conduct a malicious DDoS against someone who has possibly revealed who is operating a service and/or committing crimes? If someone posted that OpenAI had committed a crime or revealed its backers, would it be defensible for OpenAI to insert code for every ChatGPT.com visitor to make requests to that user's site every 0.3 seconds?
Or do you not think the archive.today operator's existing actions are defensible?
[–] bulder 1 day ago
[–] eyya 23 hours ago
And when you consider that Jani Patokallio isn’t just some random, curious, cybersecurity blogger, but the ~40-year-old son of a high-ranking Finnish official who suddenly took up slighting and doxing, the story takes on a whole new dimension and it’s hard to come up with a benign explanation for his curiosity: either you’re being hounded by the deep state or a wealthy nutcase.
[–] iam-py-test 13 hours ago
[–] jaychandra68 11 hours ago
Curiosity? I don't buy it. Too long and persistent.
Combined with zero curiosity on neighbor projects like 12ft or magnolia1234's bypass-paywalls-clean.
You do stalk exact people behind archive.today and btdig, for years, not investigating the niche, so don't call yourself "security bloggers" or "journalists"
[–] Ukv 1 day ago
> We verified this isn't just us or just this source (it's a link in a NYT article to a PDF anyway, about the most safe combo I can think of)
Might be able to find the article in question by looking for NYT links posted to the subreddit recently (if the presumably-deleted archive link was posted separately as a reply).
[–] avidruntime 1 day ago
That suspicion becomes more grounded when the conversation with the subreddits mod regarding why the claim was made without a willingness to provide evidence looks like this:
>If you're going to make an allegation like this, it's necessary to be specific. Specifically, what is the malware, and what is the evidence that it was "injected"? This is "consult a security researcher" and "speak to the media" territory, not "mod announcement" territory.
>>No it's not. These archive sites are a legal gray area anyway. We don't have to consult anyone to decide not to allow the links. No we are not talking to the media, we're not providing research, or a proof. I'm not calling the mayor. We are reddit mods . This is purely about community management.
https://www.reddit.com/r/Seattle/comments/1xhf6qp/archivetod...
[–] Ukv 1 day ago
Originally posted here: https://www.reddit.com/r/Seattle/comments/1xh57il/removed_by...
The "filed on Tuesday" link seems to go to gullible-thanks[.]com, which redirects to random shady sites.
[–] avidruntime 1 day ago
[–] lysace 1 day ago
Edit: Now there is something here: https://www.reddit.com/r/Seattle/comments/1xhf6qp/comment/19...
[–] avidruntime 1 day ago
Unbelievable that the comment asking for evidence sits at -24 upvotes in that thread as of now. https://www.reddit.com/r/Seattle/comments/1xhf6qp/archivetod...
[–] mahboi 1 day ago
[–] avidruntime 1 day ago
The moderators seem to be making it quite clear: they do know what is going on and the onus is not on them to prove it, only to notify actions have been taken in response. https://www.reddit.com/r/Seattle/comments/1xhf6qp/archivetod...
This attitude is extended when someone else asks a question about evidence, instead of replying to the question, the moderator sarcastically calls out the commentor for posting in the sub for the first time: https://www.reddit.com/r/Seattle/comments/1xhf6qp/archivetod...
The moderator conflates questions about evidence and requests for more details as "making demands" https://www.reddit.com/r/Seattle/comments/1xhf6qp/archivetod...
Its unusual and arguably suspicious because this attitude is antithetical to the stated point of the thread: To make a PSA to the community. They've also limited the comment section to only flaired users, which seems quite unusual given that this thread is ground-zero for a newsworthy claim.
[–] mahboi 1 day ago
[–] avidruntime 1 day ago
[–] tyrabound 1 day ago
It’s not to say it’s not so, but people are fools to just chomp down on the bait.
[–] ada-h00k 1 day ago
[–] keoneflick 1 day ago
Why should journalism be free? Is $4 not an appropriate price for real journalism? If not, then what?
Your library if it's in the US also likely maintains access to NYT archives.
[–] Dylan16807 1 day ago
Because that's not what NYT says the price is. They say it's over $30 after the intro period.
[–] ada-h00k 1 day ago
[–] strenholme 1 day ago
[–] consumer451 1 day ago
Genuine question here.
[–] strenholme 19 hours ago
[–] Brian_K_White 1 day ago
It might be useful for your own memory since you can decide that you trust what was written. IE you trust that when it was written, you agreed at the time that it was an accurate summary, and later you only have to trust your earlier self.
But "My ai said that the site said ~essentially~ this on this date." is useless for anything else.
But it suggests an interesting idea. Maybe if we had some ai equivalent of trusted vetted accountable court reporters who write down notes and draw sketches in rooms where cameras aren't allowed.
That is purely second-hand reporting that we more or less trust, partly because there is usually more than one of them from competing venues reporting on the same event, partly because they are people with something to lose if they are unfaithful or even merely inept, partly because the facts are ultimately vettable with some effort for those who really need to.
There's no such ai yet. Even if one exists that could do the job, there is no consensus or basis for it, for everyone to recognize it as a trustworthy source of second hand reporting. But maybe if there were more than one and operated by different camps, they could grow to become recognized as a valid source of info.
[–] Permik 1 day ago
[–] knowaveragejoe 1 day ago
[–] charcircuit 22 hours ago
[–] iam-py-test 13 hours ago
[–] LoganDark 1 day ago
[–] Hamuko 1 day ago
[–] LoganDark 1 day ago
[–] worksonmine 1 day ago
[–] john_strinlai 1 day ago
they are not great people.
[–] burningChrome 1 day ago
[–] MisterMunchkin 1 day ago
[–] cowlevel 1 day ago
[–] john_strinlai 1 day ago
so fucking strange that people are playing defense for that. even forgetting the DDoS part, people don't care that they are editing archived content? wild.
[–] consumer451 1 day ago
Here are my suppositions and questions:
The frontier labs feel free to use the path of least resistance to acquire more data. Currently, one of those paths must be archive.today. Proof of that is that an archive.is link is posted here on HN, for any news post, right? I certainly find those links useful.
So, now that we know that archive.today is the easiest path to paywalled data, is a threat actor, and can poison training data...
1. What is their valuation?
2. Will the labs stop using them? Is it even fair to assume that they are?
3. ... ?
[0] https://www.reddit.com/r/Seattle/comments/1xhf6qp/archivetod...
[–] eyya 1 day ago
[–] consumer451 1 day ago
But, injecting malware to scuttle their own incredibly popular network would benefit them how?
[–] eyya 1 day ago
So far, the only benefits of this popularity are the AI crawlers which cause the site to run intermittently (same issue this year with archive.org and commoncrawl) plus Finnish doxxers and fake child-porn fighters trying to shut it down.
[–] consumer451 1 day ago
Next, IIRC, one DNS provider stopped working with them for insane privacy reasons? [0]
Now, tinfoil hat time: what about the AI labs using them for training data, and it getting steered one way or another now that we know for a fact that archive is not reliable?
[0] It is Cloudflare due to EDNS Client Subnet (ECS) privacy, right?
[–] eyya 1 day ago
[–] consumer451 1 day ago
Isn't just the scale of cost indicative that is not aligned with anything close to indie?
[–] armchairhacker 1 day ago
[–] kragen 1 day ago
[–] humodz 1 day ago
[–] sfoley 1 day ago
[–] danso 1 day ago
(ofc this is a risk with the Wayback Machine, who also has a policy for honoring takedown request. But the Internet Archive's board and executives are known people with reputations)
[–] throw0101c 1 day ago
* https://news.ycombinator.com/item?id=47092006#47100204
* https://arstechnica.com/tech-policy/2026/02/wikipedia-bans-a...
[–] mahboi 1 day ago
[–] iamnothere 1 day ago
(This is why archives that bypass paywalls are particularly important. I wish we had more options here.)
[–] kvemkon 1 day ago
I think there is a confusion of blogger with a registered journalist, who must follow journalist's (ethic) rules.
[–] kragen 8 hours ago
[–] Onavo 1 day ago
[–] paulpauper 1 day ago
[–] whalesalad 1 day ago
[–] motionlessveloc 1 day ago
It also automatically redirects you to archive.today as backup if its own attempt fails.
[–] 1vuio0pswjnm7 1 day ago
Archive.today's /o/ endpoint itself returned the instruction to redirect, not the original source URL. We observed this in more formal testing on October 28, 2026, at approximately 07:35 UTC.
The link's actual href on the archived version of the page was:
hxxps://archive.ph/o/jXv3A/https://schenklawfirm.com/wp-content/uploads/2026/10/wan-v-o..."
As it happens, and this is quite common, use of archive.today was not necessry
https://www.courthousenews.com/wp-content/uploads/2026/10/wa...
No "bot protection"
[–] 1vuio0pswjnm7 1 day ago
[–] 1vuio0pswjnm7 1 day ago
Managing the client software's use of HTTP headers, Javascript and/or CSS works just fine
[–] CreepyHunterX 1 day ago
[–] slipperybeluga 1 day ago
[–] ferngodfather 1 day ago
[–] frenchtoast8 1 day ago
[–] wlonkly 1 day ago
https://en.wikipedia.org/wiki/Wikipedia:Wikipedia_Signpost/2...
[–] mahboi 1 day ago
[–] avidruntime 1 day ago
https://www.reddit.com/r/Seattle/comments/1xhf6qp/archivetod...
Not sure if this post even qualifies to be on hacker news...its all rumors and any attempt to distill the incident to its facts is met with pushback.
[–] mahboi 1 day ago
[–] avidruntime 1 day ago
[–] ballon_monkey 1 day ago
This happens on HN too.
[–] mahboi 1 day ago
[–] ballon_monkey 1 day ago
Edit: Not being able to down vote till 300 points is a good thing tho, does prevent new accounts being created just to down vote.
[–] Karrot_Kream 1 day ago
The problem isn't really the site, it's the people. People like smashing the up and down buttons on things they agree with and unfortunately a comment's score affects where it shows up on the page.